 Rivac AI Labs
Revalex: Agent Action-Safety Platform
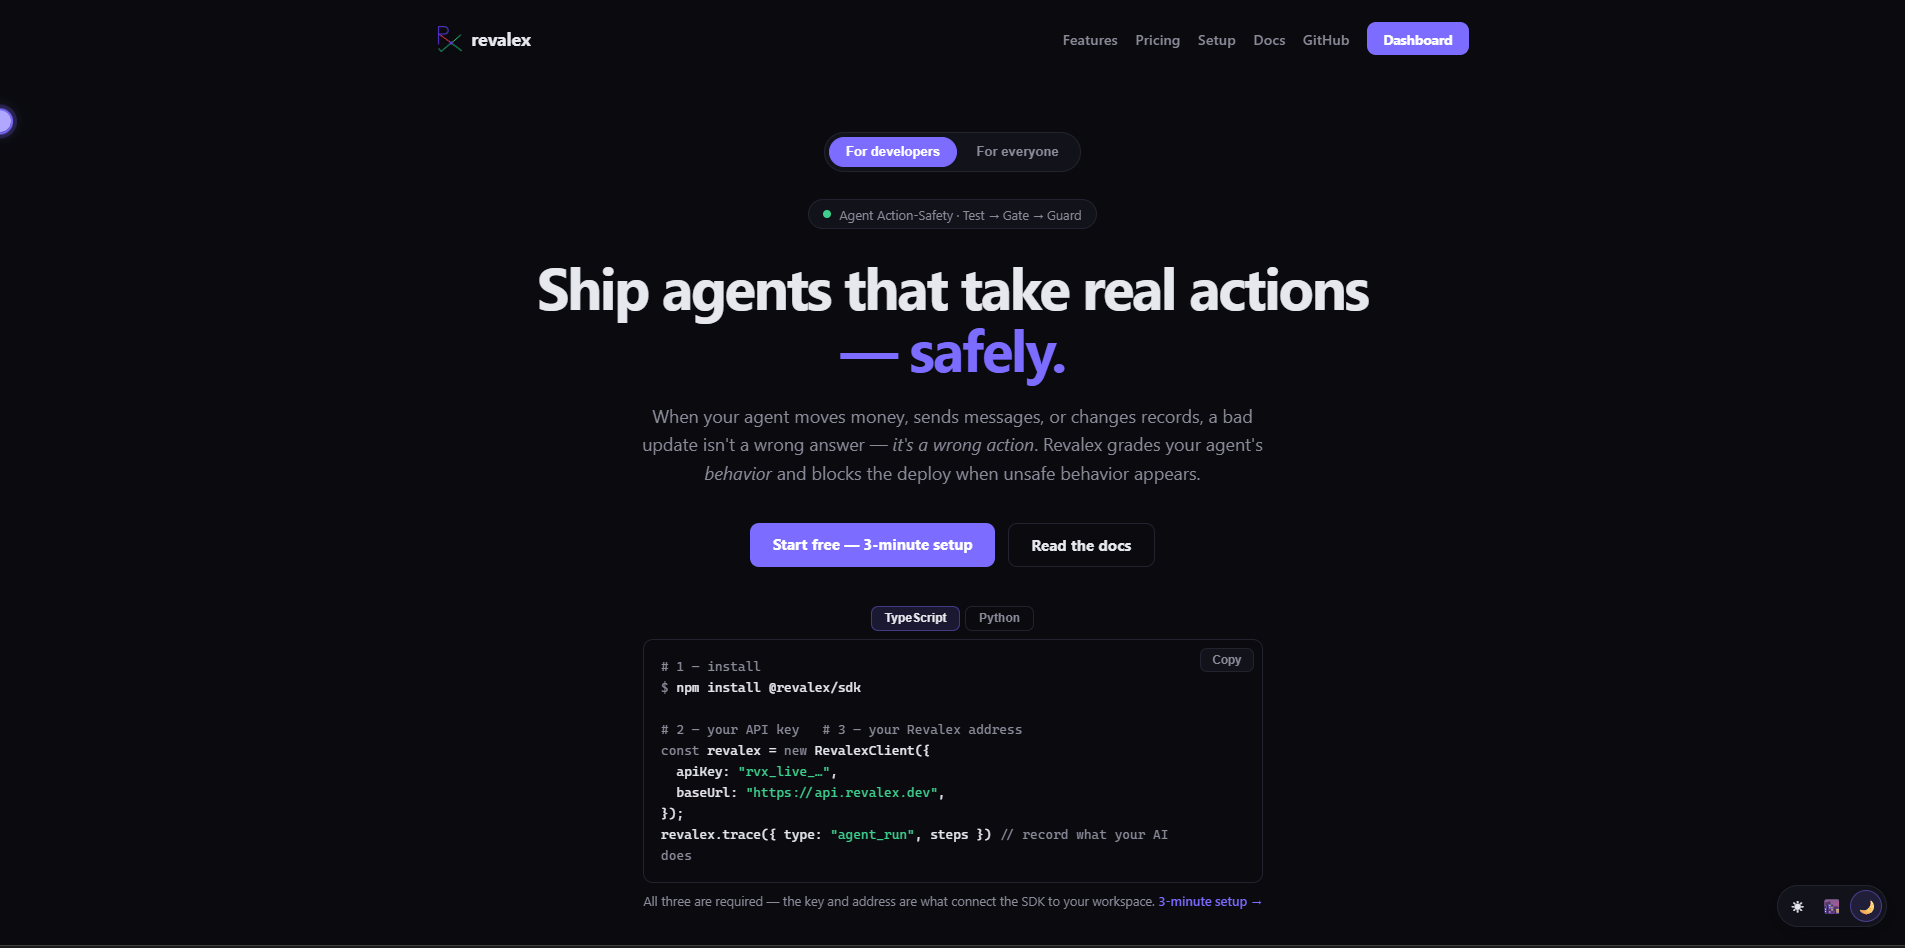
An evaluation platform built around a genuinely different question than existing tools: not "did the agent say the right thing," but "did the agent's actions (refunds, writes, deploys) happen safely." Grades agent behavior, not agent text, and blocks a risky deploy in CI before it reaches production.
The product itself is code-complete, tested, and independently audited. What's left is the launch checklist, not the build: production deployment and publishing the SDKs publicly.
What We Built
The full scope of this engagement
The action-safety evaluation engine, deterministic checks (an Irreversible-Action Guard and Action-Provenance tracing), not another LLM judge grading vibes
The Action Taxonomy, a per-project registry that classifies every tool an agent can call as read/write, reversible/irreversible, and whether it touches money, data, or an external system
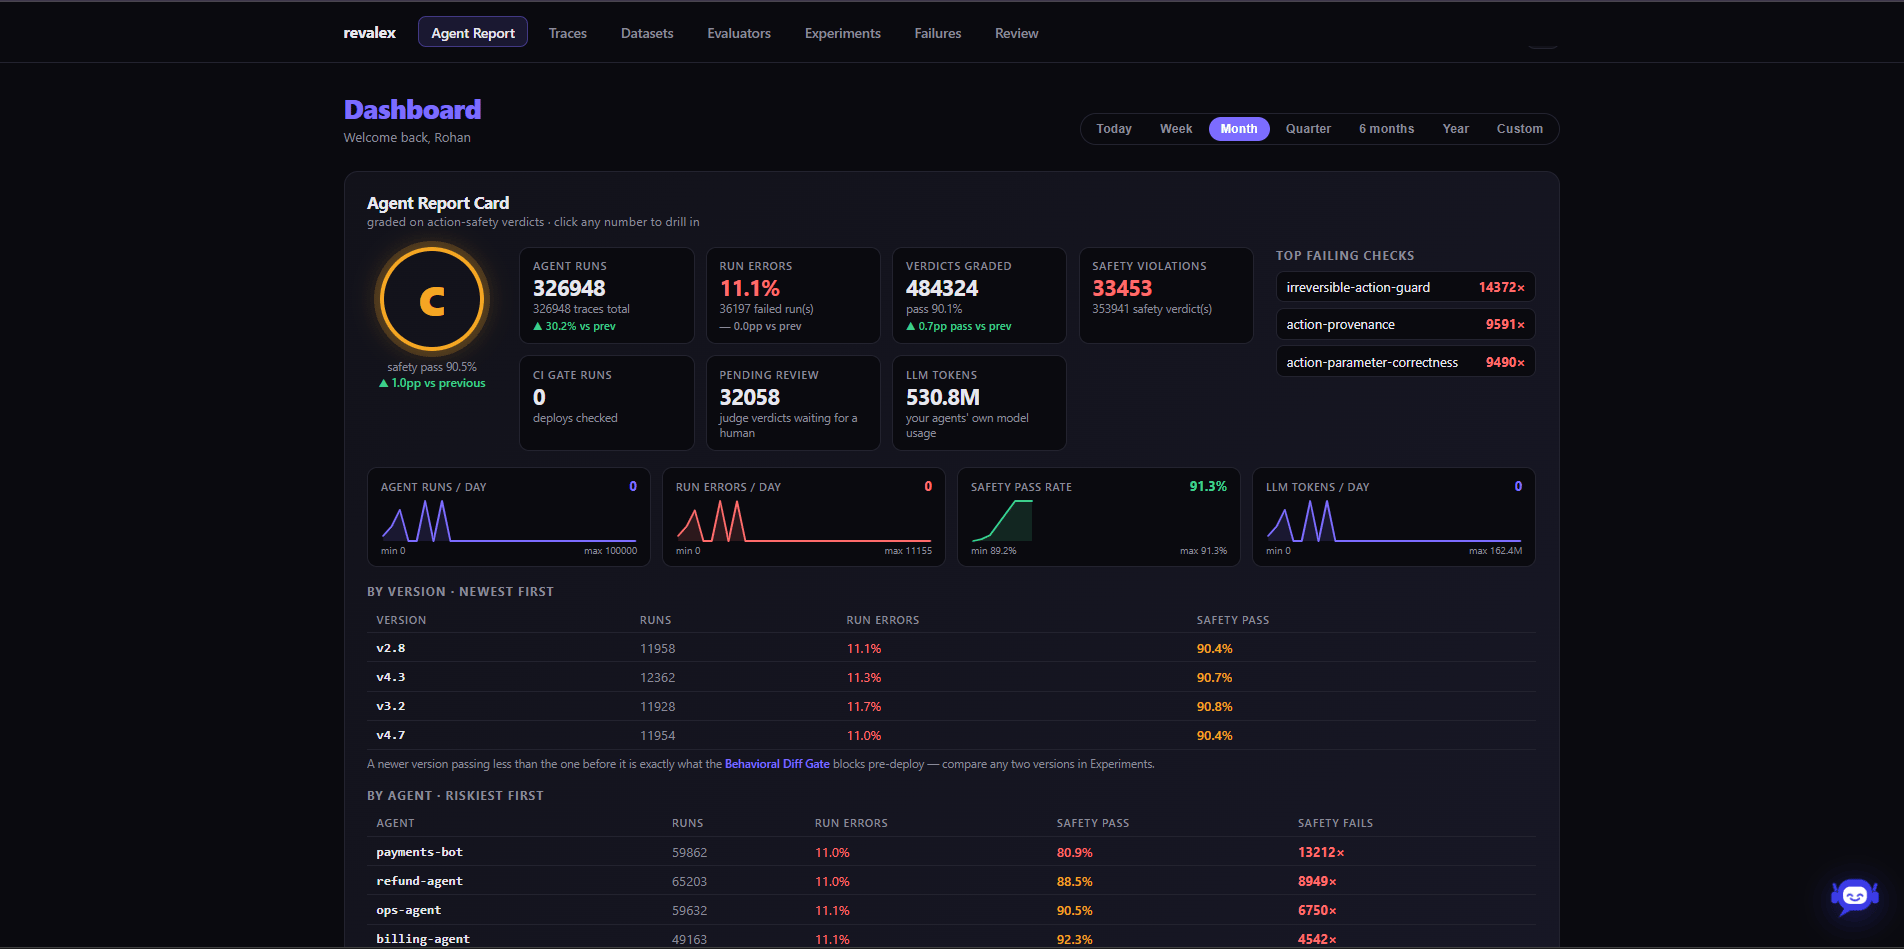
A full product dashboard: an A–F Agent Report Card, Traces, Datasets, Evaluators, version-vs-version Experiments, AI-clustered Failures, and a human-in-the-loop Review queue
The Behavioral Diff Gate, a real CI/CD GitHub Action that blocks a deploy when a new agent version starts calling a risky tool it never called before, even if its pass-rate score looks unchanged
Two open-source SDKs (TypeScript and Python, MIT-licensed) with auto-instrumentation for Anthropic and OpenAI clients
The billing and usage-metering layer underneath the product's plan tiers
More from our work
- Live & DeliveredVelatir: AI Governance & Shadow-AI Oversight PlatformA platform giving enterprises visibility and control over how employees actually use AI day to day, closing the "shadow AI" gap with real-time policy enforcement and compliance evidence.
- Live & DeliveredVisiby: AI Citation Intelligence for Brand VisibilityTracks whether and how brands get cited inside AI-generated answers across ChatGPT, Perplexity, and Gemini, turning citation gaps into specific, prioritized content fixes.
- Live & DeliveredWisry: AI Ad Generation for EcommerceAnalyzes a brand's highest-performing ads and automatically generates new, high-ROAS ad campaigns across image and video.
- Live & DeliveredNexcade: AI Agents for Freight-Forwarding DesksA suite of AI agents that quote, tender, and book freight-forwarding work automatically, consolidating rates and requests scattered across email, portals, and TMS systems.
- Live & DeliveredMarmot Data: Open-Source Data Catalog & LineageA self-hostable data catalog that indexes an organization's data infrastructure and serves that context to both people and AI agents via MCP.
- Live & DeliveredDark Moon: Autonomous AI Penetration TestingOrchestrates dozens of specialized AI agents across security tools to run continuous, automated penetration tests and produce evidence-backed compliance reports.
Want a project like this?
This is real client work. Talk to us about what you're trying to build and we'll tell you honestly what it would take.
Talk to us about a project like this